Same old 8 GB card — once I added QuantFunc to ComfyUI, it renders nearly 5× faster than native.
Speed vs the FP8 version of the same model, measured on an RTX 4090 with our published models (MiniMax-H3: time per step at 768×768, 124 frames; Krea-2: denoising). Up to 11× on 8 GB / 12 GB cards (Krea-2). Actual speed varies with resolution, frames, steps, driver and software. Benchmarks & methodology →
Every image below was generated locally in 1–2 seconds:
Once it’s installed, they don’t go back
"Running Flux on 8 GB now — nearly 5× faster than native. Installed it and never looked back."
"Didn’t change a single node — wired it in and got 6× instantly. auto_optimize just works."
"With render times gone, client revisions barely wait anymore. We iterate several more rounds a night."
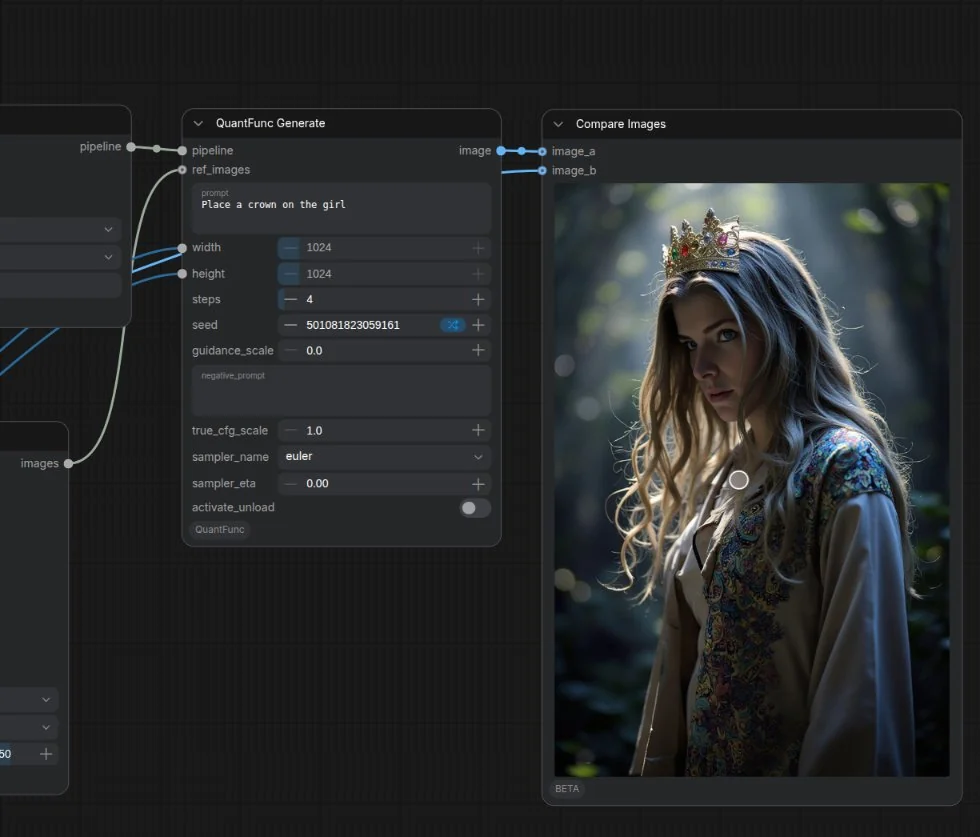
"Qwen-Image-Edit follows my edit prompts precisely and keeps the rest of the image intact — a 1536² edit takes just seconds on my 12 GB card, all local."
Speed vs the FP8 version of the same model, measured on an RTX 4090 with our published models (MiniMax-H3: time per step at 768×768, 124 frames; Krea-2: denoising). Up to 11× on 8 GB / 12 GB cards (Krea-2). Actual speed varies with resolution, frames, steps, driver and software. Benchmarks & methodology →
Same card, several times faster
Measured on an RTX 4090 against the FP8 version of the same model — and on 8 GB / 12 GB cards the gap grows to as much as 11×.
Speed vs the FP8 version of the same model, measured on an RTX 4090 with our published models (MiniMax-H3: time per step at 768×768, 124 frames; Krea-2: denoising). Up to 11× on 8 GB / 12 GB cards (Krea-2). Actual speed varies with resolution, frames, steps, driver and software. Benchmarks & methodology →
Drop-in — no workflow rewrite
Clone into custom_nodes and restart ComfyUI (the engine installs itself). Put the QuantFunc loader for your model where the diffusion-model loader goes; ComfyUI's own text encoder, VAE and KSampler stay as they are.
1cd ComfyUI/custom_nodes2git clone https://github.com/QuantFunc/ComfyUI-QuantFunc.git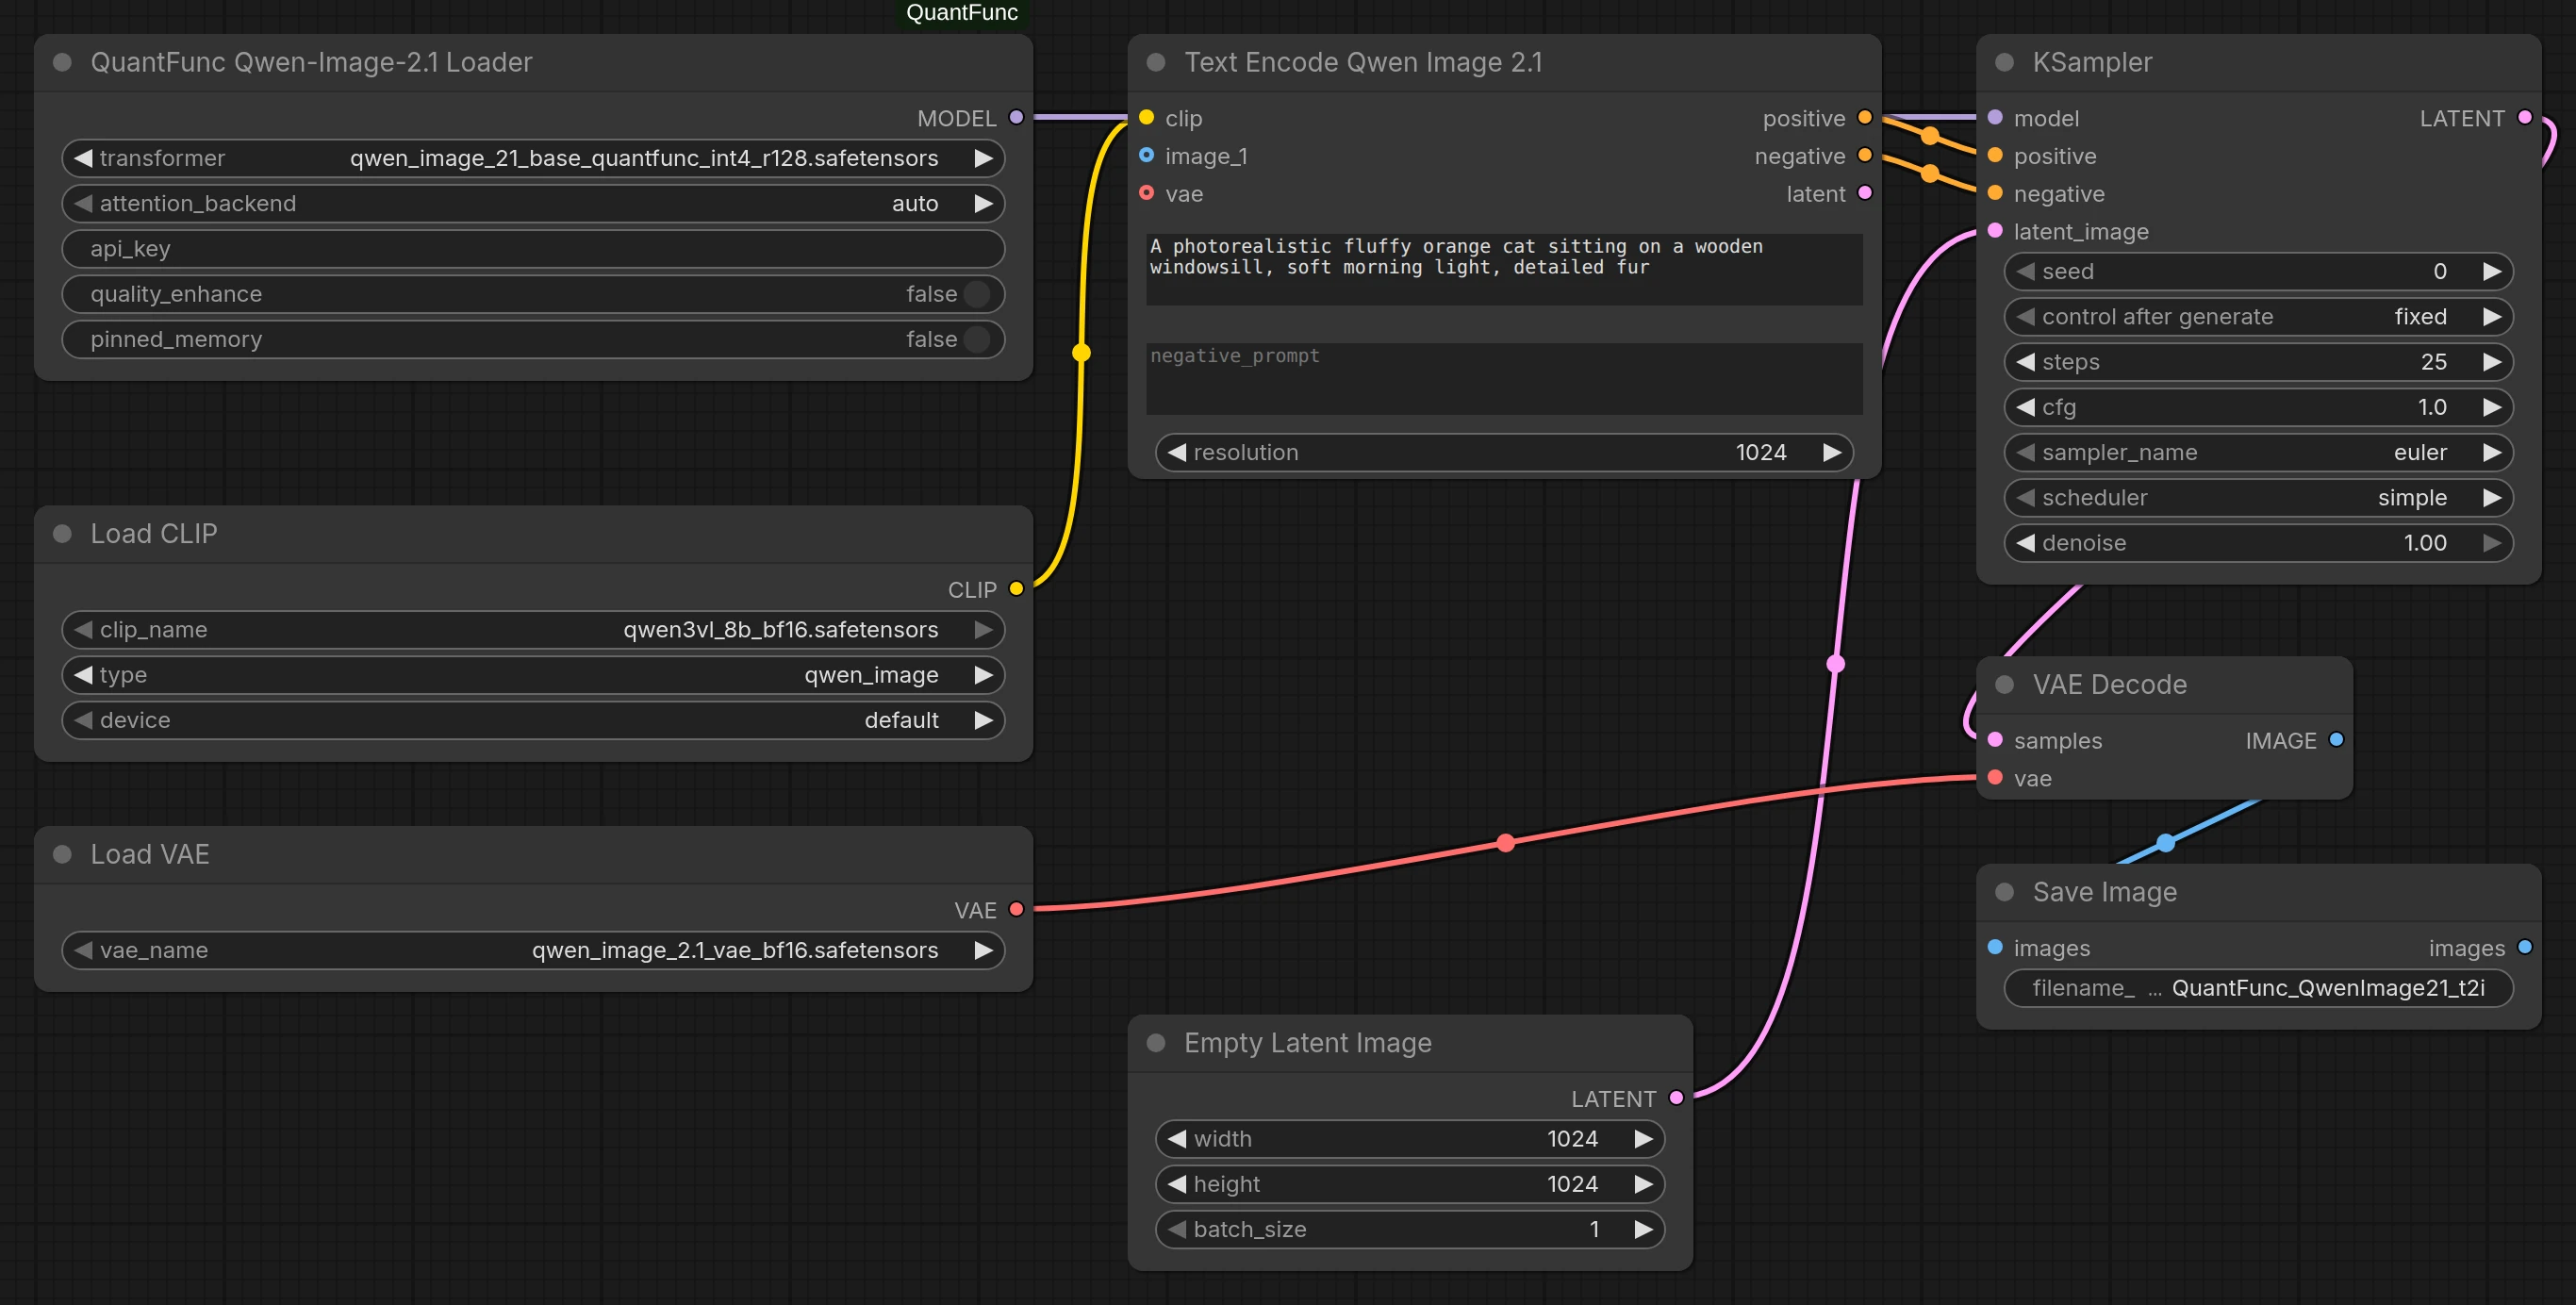
INT4 — 4-bit, almost no quality loss
QuantFunc INT4 takes the core weights from 16-bit to 4-bit — about a quarter of the size — while keeping detail, and CUDA 12 / 13 precompiled kernels deliver 0 ms JIT stall.
Core weights go from 16-bit to 4-bit, about a quarter of the size, and still keep high quality.
Native 4-bit INT4 quantization slashes VRAM with near-zero quality loss.
CUDA 12 / 13 precompiled kernels — no first-frame hitch, no model-swap wait.
Supported models
Speed vs the FP8 version of the same model, measured on an RTX 4090 with our published models (MiniMax-H3: time per step at 768×768, 124 frames; Krea-2: denoising). Up to 11× on 8 GB / 12 GB cards (Krea-2). Actual speed varies with resolution, frames, steps, driver and software. Benchmarks & methodology →
Explore all our quantized models onModelScope·Hugging Face
We never charge for any model. Please comply with each original model's license.
Call it from your own code
The Python SDK, C API and CLI are coming soon — 50% faster than the ComfyUI plugin, for teams that build the engine into their own systems.
faster than the ComfyUI plugin
Video workflows are here
MiniMax-H3 and LTX-2.5 now run in QuantFunc — video with sound, generated on your own GPU, with MiniMax-H3 3.19× faster per step than FP8.
Runs on 8 / 12 / 16 / 18 / 20 / 24 GB
QuantFunc models take part in ComfyUI's own memory management, and when the card can't hold all the weights the engine streams the rest from system memory instead of failing — so consumer GPUs run models that used to demand 24 GB.
Start free, upgrade when it flies
The ComfyUI plugin is free, with unlimited images and videos. Paid plans are for the SDK — for developers who build the engine into their own systems: PC plans for fixed devices, Traffic plans for cloud servers.
Register and go, per device
Bind 1 device — unlimited for the term
Bind 5 devices — unlimited for the term
Domain / org binding, deeper discounts
All plans are free during the public beta — there's nothing to pay. The pricing below is for reference.
Each API key activates one plan. Upgrade within a type; switching types isn’t supported — need both PC and Traffic? Claim a separate API key for each. All quotas reset weekly. Paid plans auto-renew and can be cancelled anytime (effective at the end of the current period).
Your workflow runs on firmware you can trust
Generation stays local — verifiable firmware, controllable keys, data never leaves your machine.
SHA-256 firmware checks
Every plugin and kernel binary ships a SHA-256 fingerprint, verified on download — no tampered firmware.
Third-party audits
Independent security audits and compliance certs are in progress, with public results.
Least-privilege keys
Rotate or revoke API keys anytime; runs at least privilege so a leak is contained instantly.
Local inference, no exfil
Generation runs on your own GPU — prompts and images never leave your machine.